
It’s Tuesday afternoon, and the best internal developer just blocked the calendar for two weeks. Everything is fine here at lab. It’s still producing here. Ordering has been received; Sample data is being recorded; Results entered; Report generation done; Billing closed for this cycle.
A request to make some minor changes is made. One of these is missing a client name, another is that there’s been an update to change a formula in analysis form, and finally there’s been a price override that only one developer is responsible for. It’s not due to irresponsibility of this team, but because there are no other people available to do this job while they are out of work.
Several years ago, there was an experienced programmer who knew how to let the system grow around him. It’s also much more complex now with more report types (and their formats), more types of analysis, and an online Web version of that same thing. A lot of work is still with a single individual.
You will learn:
- How a strong internal developer is a single point of failure when scaling up.
- Five processes to block immediately if this person isn’t available.
- A 15-minute way to stress test each one.
- Warning signs to recognize when something is going wrong and needs immediate attention.
- An 8-point Laboratory Internal Continuity Checklist.
- How a real environmental testing laboratory reduced that concentration of knowledge without ripping out the system they already depended on.
Quick Takeaway for Laboratory Leaders
If your lab runs on a LIMS, an internal platform, or a hybrid desktop/web system, one person who “just knows” how it works is a single point of failure – the same way an instrument, a network link, or a key vendor contact is. You don’t have to be distrustful of him/her while planning it out. Generally speaking, this is usually one of those reasons why it works even now and then.
Just accept it, people go on vacation, change jobs, get sick and run out of time. It does not stop at all these.
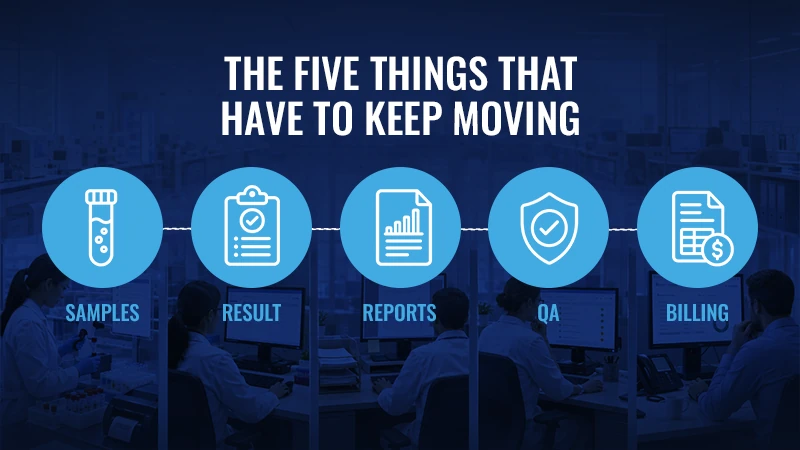
Five workflows to safeguard are the ones that keep a lab running day to day:
- samples — order, chain of custody, distribution to analysts
- results — entry, review, analysis-specific data capture
- reports — generation, formatting, delivery to clients
- QA — review, amendments, defensibility of results
- billing — pricing, invoicing, revenue timing
If you cannot say, with evidence, that each of these can keep moving without that one person’s immediate involvement, that is worth fixing before it becomes urgent.
This Article Is for You If
This is relevant if your laboratory:
- Runs on a LIMS or custom platform that one internal person (or one contractor) understands much better than everyone else.
- Has seen a lot of enhancement requests coming through one person’s email address.
- There is very little information available for another person to do what this engineer does.
- Still depends on desktop workflows that “only X knows how to change”.
- Has never actually tested what happens if that person is out for two weeks.
- Deciding if we should hire someone else, hire a contractor or hire more help keep hoping for it to work out.
One Strong Developer Is Not the Problem
One internal developer problem is usually not due to bad hires. Generally speaking its usually due to an excellent one.
Someone knew how to use it before things got bigger. They fixed the ugly parts. They remembered the exceptions. They were the shortest way to go from “we need this” to “it works.”. The managers went to them. The analysts went there.
With passing of time, the map of the system was kept by a person and not by an organization. It’s not one of your character’s flaws.
How busy lab work gets done with limited manpower and existing software that tracks sample data, report generation, quality assurance and billing:
- More types of analysis, more edge cases, more client formats.
- A Web layer on top of mature desktop workflows.
- The same person still owning changes, emergencies, and tribal knowledge.
- Documents never got written as shipping was always first priority.
Single point of failure is blamed on vendors all the time. Internal ones are missed as they sit at a desk answering Slack messages. Until they are not.
The Five Things That Have to Keep Moving
For a laboratory, “keep the business moving” is not abstract. It comes down to five workflows, and each one has a different failure mode when the person who carries the system is unavailable.
| Workflow | What “Still Moving” Looks Like | What Stalls First When One Person Is Out |
|---|---|---|
| Samples | Orders are created, chain of custody is logged, samples are distributed to the right analysts | Sample routing, batch assignment, or distribution rules that only one person can safely change |
| Results | Analysts enter results into the correct forms for each analysis type | A form bug, a new field, or analysis-specific logic that nobody else will touch |
| Reports | Clients receive accurate, on-time reports in the format they expect | A template fix or a client-specific field that waits on the one person who owns reporting |
| QA | Results are reviewed, amended, and defensible under audit | QA / QC rules and review paths that are opaque outside one developer’s notes |
| Billing | Pricing is applied correctly, and invoices go out on schedule | Pricing exceptions and invoice logic that live in code only one person has opened recently |
Walk through each one for your own laboratory, honestly.
Samples
Orders are received; there’s a record of their movement (chain of custody); samples are collected at intake and then distributed to analysts. If there is nobody that knows about sample distribution and batch assignment then a routing bug does not wait politely. It is waiting for them to come back.
Results
Analysts enter data for a particular type of analysis form. Optional nested data, status panels, signatures, QC review – all of it sits on top of rules that are easy to break if you do not know the history. If only one developer will change that logic, data entry stalls, and everything downstream stalls with it.
Reports
Customers want timely report. Regulatory turnaround windows do not stop for a developer’s PTO. If you need to modify an existing report template, or if you want to add another field that has been done by only one person then your clients will suffer from this delay.
QA
QA, QC review, amendments, and audit trails are what make laboratory results valid. If those rules are not something a second person can explain or adjust, you are relying on one calendar to protect the credibility of your results.
Billing
A revenue does not wait to return from vacation. If pricing logic, customer-specific rates, or invoice generation live in code only one person maintains, a two-week absence shows up on the books, not just in the IT backlog.
The 15-Minute Absence Test
No need for an audit to get your first impression of it. Ask three questions for each of the five workflows above.
- Could someone other than that one developer make a small, safe change here this week.
- Is there any documentation for someone else (new member) joining us at work or partnering with us.
- If that developer did not respond for 14 days, what would break first.
The Warning Signs Before It Becomes an Emergency
They tend to appear subtly. They are all easy to explain away by themselves.
- All enhancement requests go to one name regardless of who else is working with them.
- “Don’t touch that module” is an informal policy.
- Production waits on availability of an individual rather than having an on call schedule.
- The person who knows the system is also the person writing the docs – so the docs stay thin.
- Desktop and web both matter, but only one person can move comfortably across both.
- The manager is happy if he is at work, and a little bit stressed out when they are not.
None of them are saying that a programmer has done anything bad here. They are still focused on a single location for laboratory continuity.
The 8-Point Laboratory Internal Continuity Checklist
Before assuming that you are covered, check these eight areas.
- Absence baseline: What happens, in practice, when that developer is out for a week. Not contractually. Actually.
- Single point of knowledge: Is there a person who “knows” how a critical process works, with nothing written down.
- Documentation reality check: Could a new engineer start up on your system from what is actually documented – not from what everyone assumes is documented.
- Database visibility: Is there more than one person with an understanding of database structure and rules that are sitting on top of it.
- Change request backlog: How many pending requests are sitting behind that one person right now, and how long has the oldest one been waiting.
- Emergency path: What if something went wrong with production today, and that person was unreachable, who fixes it, and how fast, realistically.
- Cross-surface coverage: Does more than one person understand how those pieces connect if you run desktop plus web plus API against one database.
- Second set of hands: Is there anyone else – internal or contracted – who could keep samples, results, reports, QA, and billing moving for a month without that one developer.
If more than two or three of these come back “no” or “not sure,” your lab is more dependent on a single person’s bandwidth than it looks day to day. A lack of it would affect you directly and not only through your backlog.
What This Looked Like for One Laboratory
We have spent the last couple of years supporting a US environmental testing laboratory on a mission-critical hybrid LIMS mature desktop workflows, a growing API layer a web frontend for bench work and a shared SQL Server database underneath all of it.
It did not fail. It had grown. The desktop was operational all through a day. Tablet and web work was expanding for analysis entry. Assignment rules, QC separation, report paths, and billing logic mattered – and too much of the working knowledge still sat with too few people.
Instead of waiting for an absence or a departure to become a crisis, the lab was focused on spreading that load while keeping the legacy platform in production. It wasn’t to rip and replace. Continuity it is, same thing and more than one person to do it safely.
That work included:
- Documenting workflows and database structure that had never been fully written down.
- Taking on specific enhancements in parallel so everything did not queue behind one overloaded name.
- Modernizing PLM result entry to the web without replacing the core desktop LIMS.
- Maintaining a stable and functional old computer system all through.
- Shared engineering coverage so samples, results, reports, QA, and billing did not depend on a single calendar.
Samples, results, reports, QA, and billing were always moving forward throughout this process (modernization), not backwards. No downtime. No forced migration. The continuity was a product and not an entirely new screen.
It wasn’t because this programmer did badly. It was about how legacy systems were too big for one person to manage them on their own and fixing it is an organizational issue rather than a people problem.
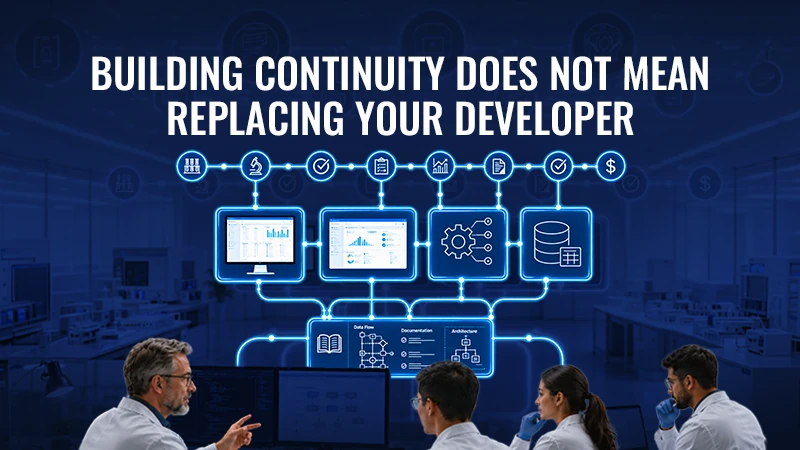
Building Continuity Does Not Mean Replacing Your Developer
There is nothing to push out that this person that is running a system. Continuity means:
- Second pair of eyes for code and database even if they are not doing all of the daily work:
- Information which is not owned by a single individual.
- The ability to do small, safe changes quickly without waiting for a whole month to pass before they can be done again.
- A clear map or transparent record of who owns samples, results, reports, QA, and billing when the usual person is unavailable.
It’s, however, is not so much about not having any of your best developer ever taking time off work; never getting burned out; and never getting a better job offer.
Generally**The user is usually more stressed out when it comes to this thing. The load spreading helps them out and is also an insurance policy to their lab.
Before Tomorrow Comes
Ask the direct version of the question this article opened with.
- If our key internal developer is unavailable starting today, what is the first workflow that stops.
- How long can we continue to run on what other people already know how to do.
- Other than this individual, who else understands it so well that they can keep it going.
If the honest answer is “we don’t know”. It is simply a no test yet.
Brain Station 23 helps lab and testing companies maintain this kind of continuity – through documentation recovery, database visibility, workflow modernization, and dedicated engineering support – so that samples, results, reports, QA, and billing keep moving no matter what happens with any single person’s availability.